A system can return a convincing answer, pass its integration tests, and still give a customer information that is factually wrong.
That is one of the most difficult changes generative AI introduces into software engineering. Traditional applications generally operate within defined rules and expected outcomes. Large language models introduce variability, context sensitivity, and outputs that can appear correct even when they contain factual errors, omissions, or unsupported assumptions.
For CTOs bringing AI-powered capabilities into production, this changes how software quality needs to be evaluated. The familiar testing process remains necessary, but the behavior of probabilistic systems requires additional criteria, continuous observation, and clearer responsibility for what reaches the user.
Traditional applications generally operate within defined rules and expected outcomes.
A passing test can still hide an unreliable answer
Consider an AI assistant integrated into a customer service platform. A user asks whether a flight can be changed without additional fees. The assistant responds confidently that changes are free up to 24 hours before departure, although the company’s policy only allows free changes for certain ticket types.
The application may be working exactly as designed from an infrastructure perspective. The API is responding, the interface is functioning, and the model is generating coherent language. Yet the answer creates a customer expectation the business cannot fulfill.
Similar problems appear in legal information, financial services, healthcare, and enterprise workflows. Their consequences depend on how much authority the system has and what users do with its outputs.
This creates a difficult engineering challenge. A model can generate multiple valid responses to the same request, making exact text matching an unreliable measure of quality. At the same time, seemingly reasonable responses can contain subtle errors that require business context to identify.
Quality assurance now needs to evaluate meaning, factual accuracy, context, and consequences alongside conventional software behavior.
The risk grows as AI becomes part of real workflows
Early demonstrations offer a controlled environment. Teams can select prompts, review outputs manually, and correct failures before anyone outside the project encounters them.
Production introduces conditions that are harder to anticipate. Users ask incomplete questions, provide ambiguous context, combine requests, and interact with the system in ways developers may never have tested.
Model updates, prompt changes, and modifications to connected data sources can also affect previously acceptable responses. A workflow that performed well during initial testing may behave differently after an underlying component changes.
Several failure modes deserve particular attention:
- Hallucinations, where the system generates information unsupported by the available facts or evidence.
- Context errors, where a plausible answer responds to an interpretation different from the user’s actual intent.
- Omissions and bias, where important information or relevant groups are excluded.
- Security failures, where manipulated inputs cause the system to disregard intended restrictions or expose sensitive information.
The challenge becomes more significant as organizations introduce AI agents capable of interacting with customer records, retrieving internal information, or initiating actions across connected systems.
An incorrect answer can influence a decision, while an agent with execution permissions may turn an incorrect interpretation into an operational action.
The engineering team must account for both possibilities.
Testing needs to follow the system into production
Generative AI requires an approach to quality that accommodates multiple acceptable outputs while maintaining measurable standards.
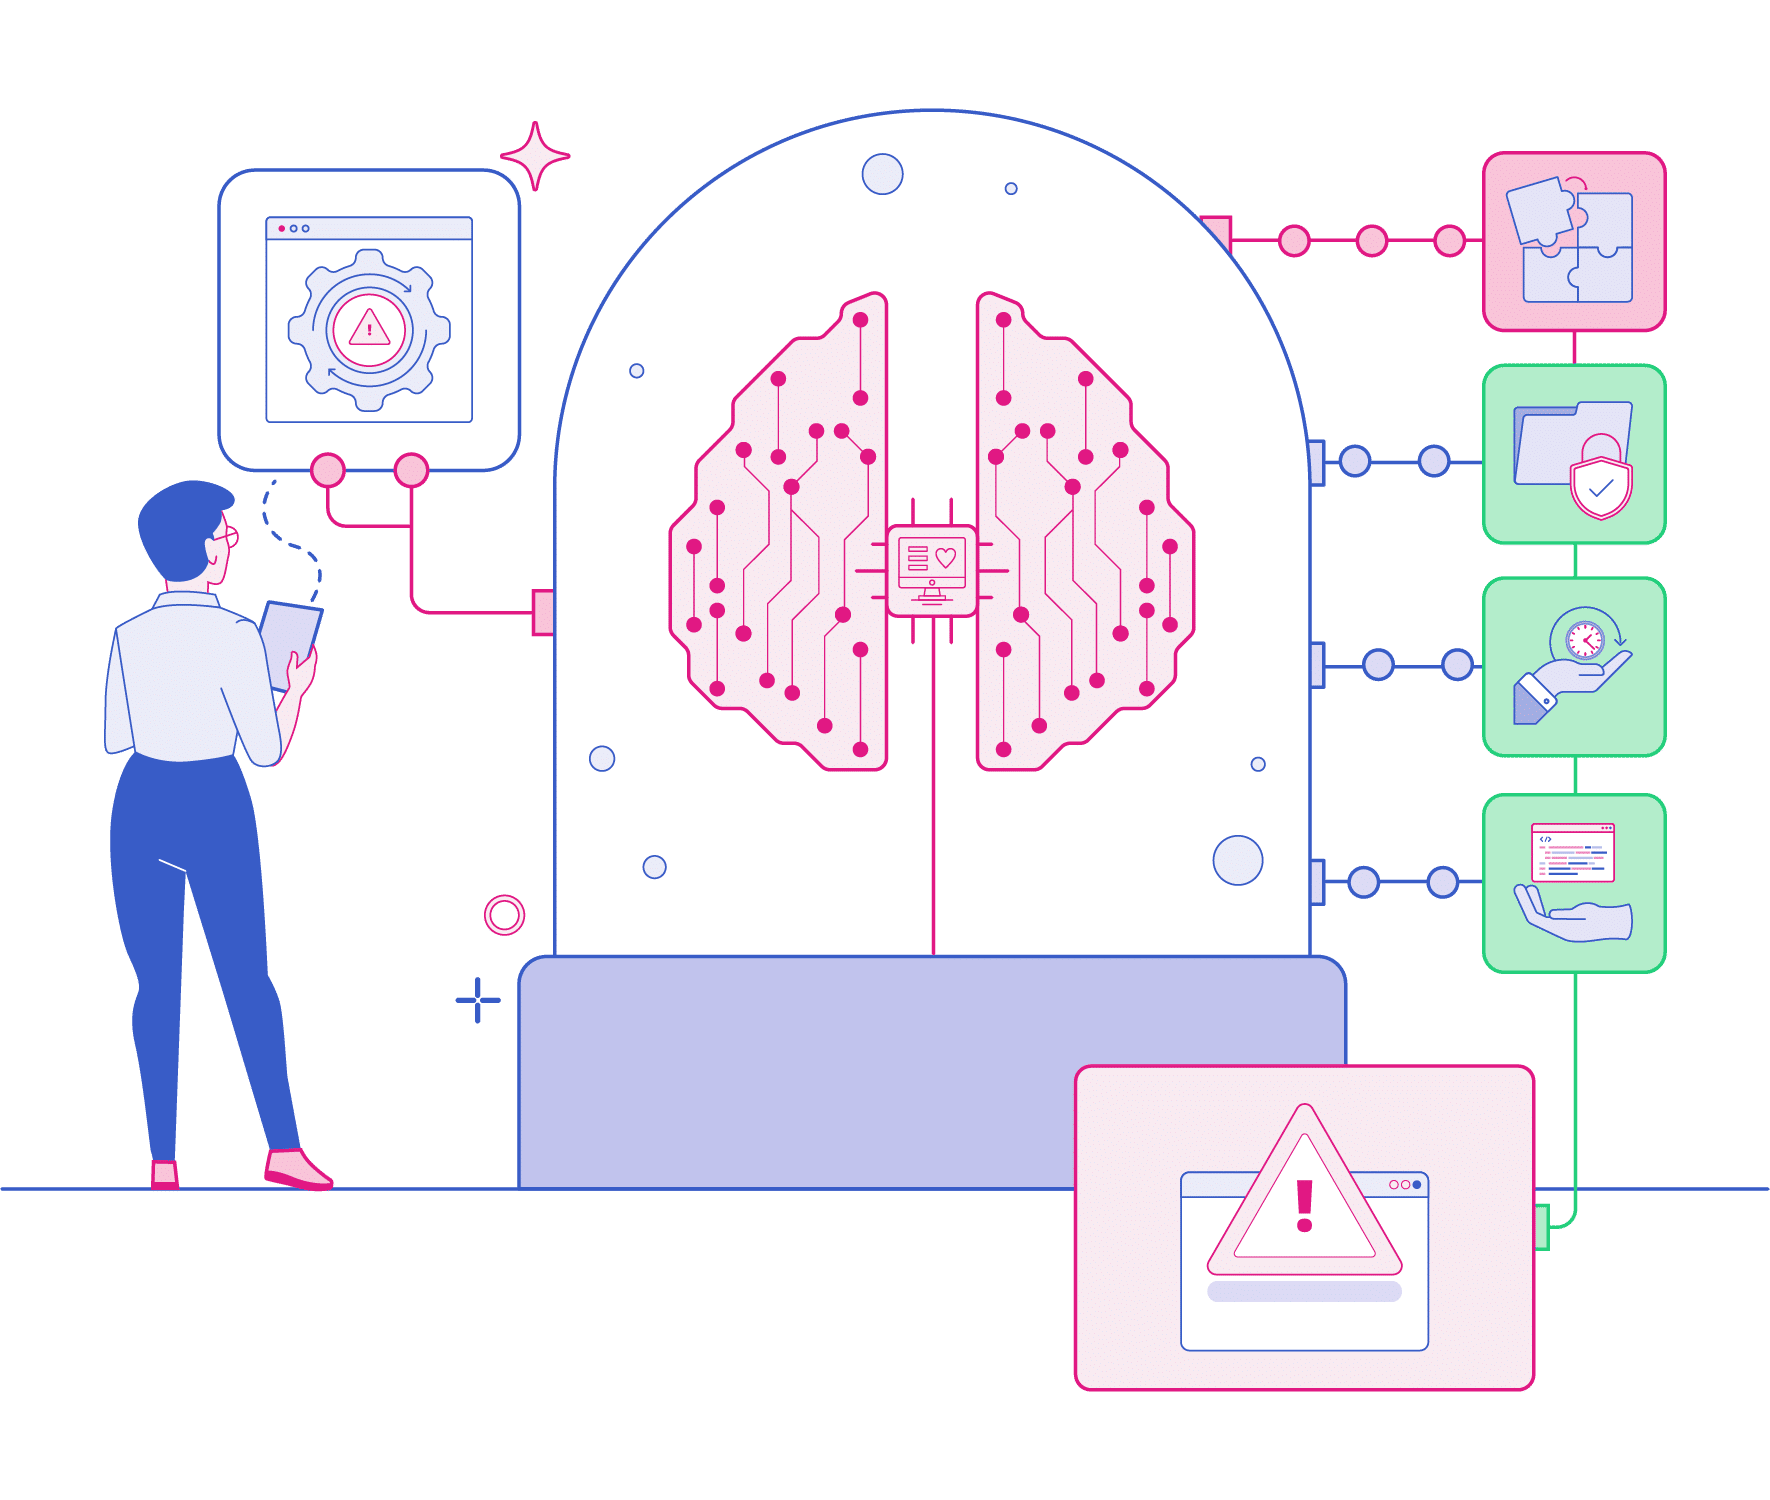
Functional testing can evaluate whether responses are grounded in available evidence, relevant to the request, and consistent with business rules. Non-functional testing adds security, harmful content, bias, and appropriate behavior under difficult inputs. Performance testing remains essential for latency, stability, scalability, and token-related costs.
These dimensions become more useful when connected to real use cases. An assistant answering general product questions may tolerate more variation than one retrieving regulated information or supporting an operational decision.
The level of validation should reflect that difference.
Tools such as Ragas, LangSmith, and TruLens can support evaluation and observability through metrics, traces, and analysis of model behavior. They help teams identify patterns, compare responses, and investigate failures.
Automated evaluation also introduces limitations. Using another LLM to judge an answer can support broader testing, but the evaluator may have its own biases, errors, or contextual misunderstandings. Human review remains important for sensitive decisions and business-critical behavior.
A practical quality process should combine automated evaluation with explicit business criteria and human oversight.
Human review remains important for sensitive decisions and business-critical behavior.
Build validation around the consequences of failure
Engineering leaders need to define acceptable behavior before evaluating whether an AI system is ready for production.
That starts with understanding the workflow, the available data, the system’s permissions, and the operational consequences of an incorrect response.
A useful review should clarify five areas:
- Context and accuracy: What information must support the response, and how will unsupported claims be detected?
- Business rules: Which constraints must remain consistent across different valid responses?
- Failure boundaries: What actions or recommendations require escalation or human approval?
- Continuous evaluation: How will changes in models, prompts, and data sources be tested and monitored?
- Accountability: Who investigates failures, approves changes, and maintains quality after deployment?
These criteria also help teams prioritize testing under delivery pressure. Higher-consequence workflows deserve deeper validation, even if that means releasing a narrower scope.
A smaller release with clearly evaluated behavior may offer a more manageable path into production than expanding functionality while leaving critical assumptions untested.
Coorva’s point of view
Generative AI is changing how engineering teams define and evaluate software quality. As systems become more probabilistic, technical leaders need to account for behaviors that traditional testing methods may struggle to detect, especially when AI-generated outputs influence real users, business decisions or critical operations.
At Coorva, we believe quality should be treated as a continuous engineering responsibility, with validation and risk assessment embedded throughout the software development lifecycle. That requires clear acceptance criteria, appropriate testing methods and human oversight proportional to the consequences of failure.
The level of autonomy given to AI also deserves careful consideration. A system that retrieves information, one that recommends decisions and one that executes actions introduce different levels of exposure. Each requires boundaries, evidence of acceptable behavior and clearly assigned ownership.
For CTOs and engineering leaders, this creates an important responsibility. As AI capabilities expand, teams need to preserve the ability to understand, evaluate and challenge what their systems produce. The reliability of AI-enabled software depends on the engineering judgment and accountability surrounding it, from development through production.
Coorva’s point of view
If your team is integrating generative AI into customer-facing applications or critical workflows, we’d like to hear what challenges you’re facing with testing, reliability, or production readiness.
Talk to Coorva about where your AI implementation may need stronger validation, engineering oversight, or operational accountability before technical exposure becomes a production problem.